You write a scraper, it works, and a week later the site changes its layout and everything breaks quietly. Build one that repairs itself instead, run it from your coding agent, and spend the week turning the data into something real.
Top 50 submissionsEvery one of them gets WeMakeDevs swag
When
August 17–23, 2026
Where
Hybrid: online from anywhere, plus a day in San Francisco
Teams
Solo or up to 4 people
Prizes
$15,000 in prizes including NVIDIA DGX Spark, iPads, Keychrons
01 / In photos
The morning this ran in a room
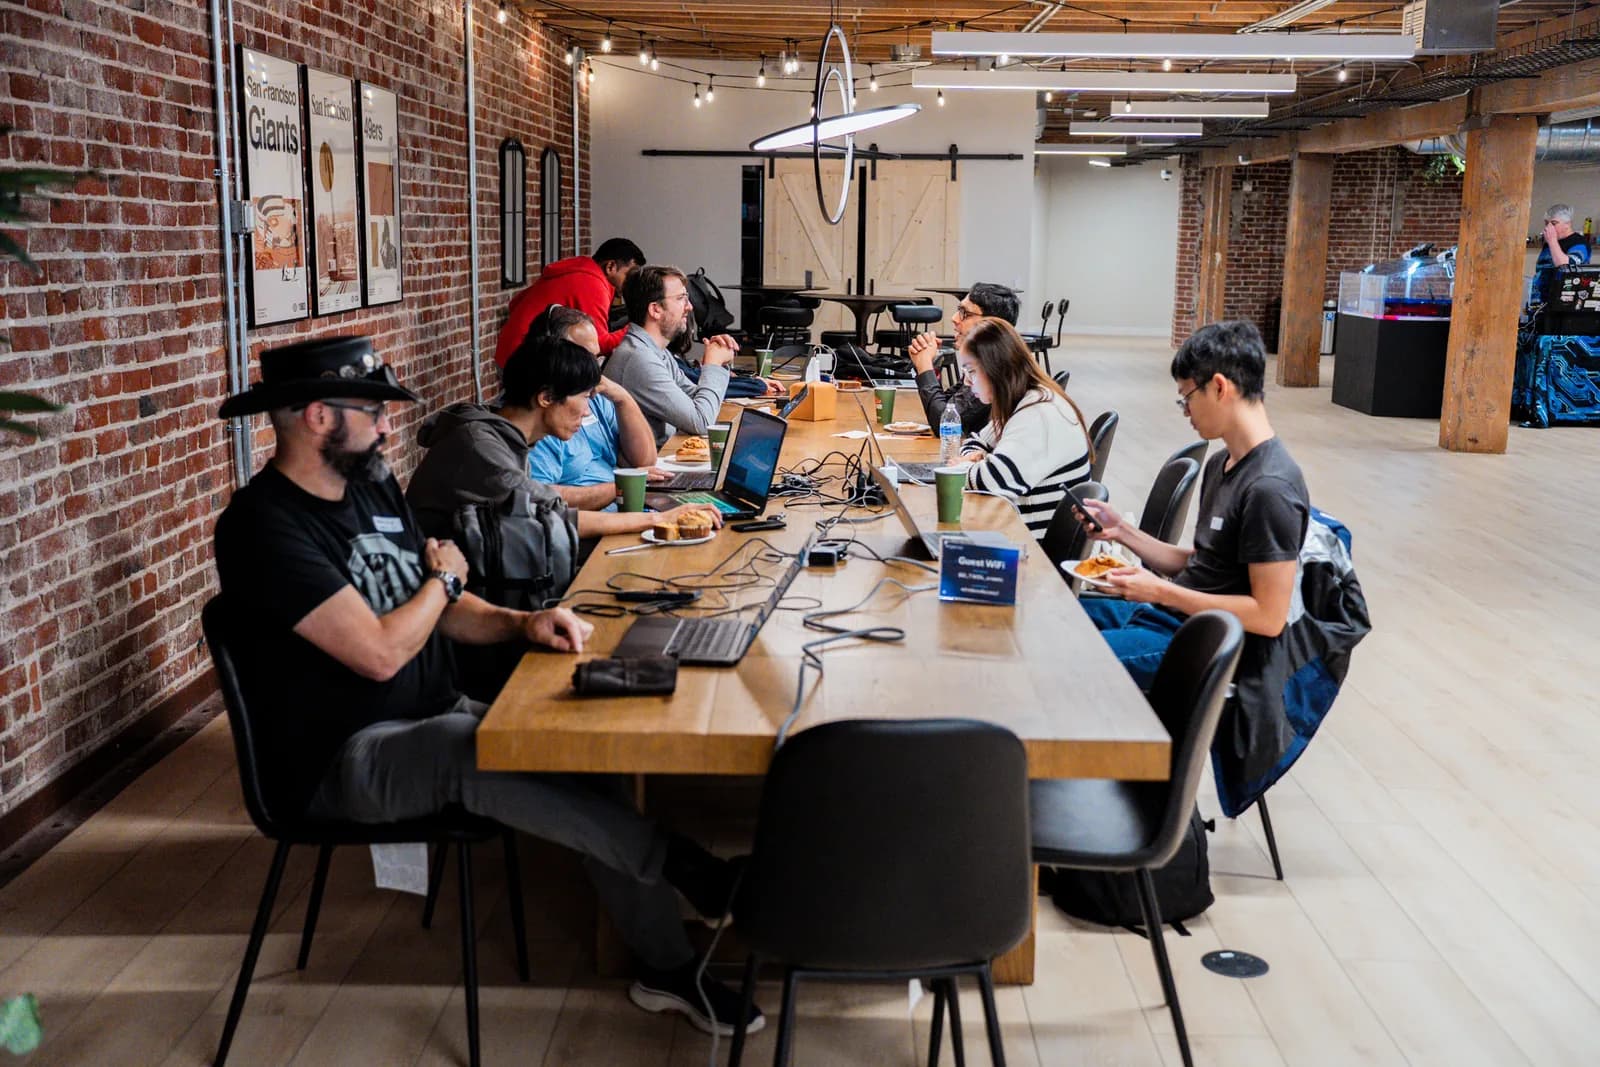
8 photographs from Zero Downtime, the in-person day of this hackathon, held in San Francisco on August 22, 2026.
01 / 08
01 / San Francisco
Doors open
Twenty past nine, one long table, and most of the chairs around it still empty.
02 / Prizes
$15,000 in prizes, and a supercomputer at the top
Four judged tracks and a raffle nobody has to build for. The iPad and the keyboard go to every member of the winning team.
Grand prize · Web-Slinger track
NVIDIA DGX Spark
Personal AI supercomputer
Prize value
$5,000
To the winning team
Best Use of Bright Data
The submission that gets the most out of the platform: the scraper you designed in Scraper Studio, how you drove it from your coding agent, what it did when the site changed under it, and what the structured output went on to power.
Suit-Up track
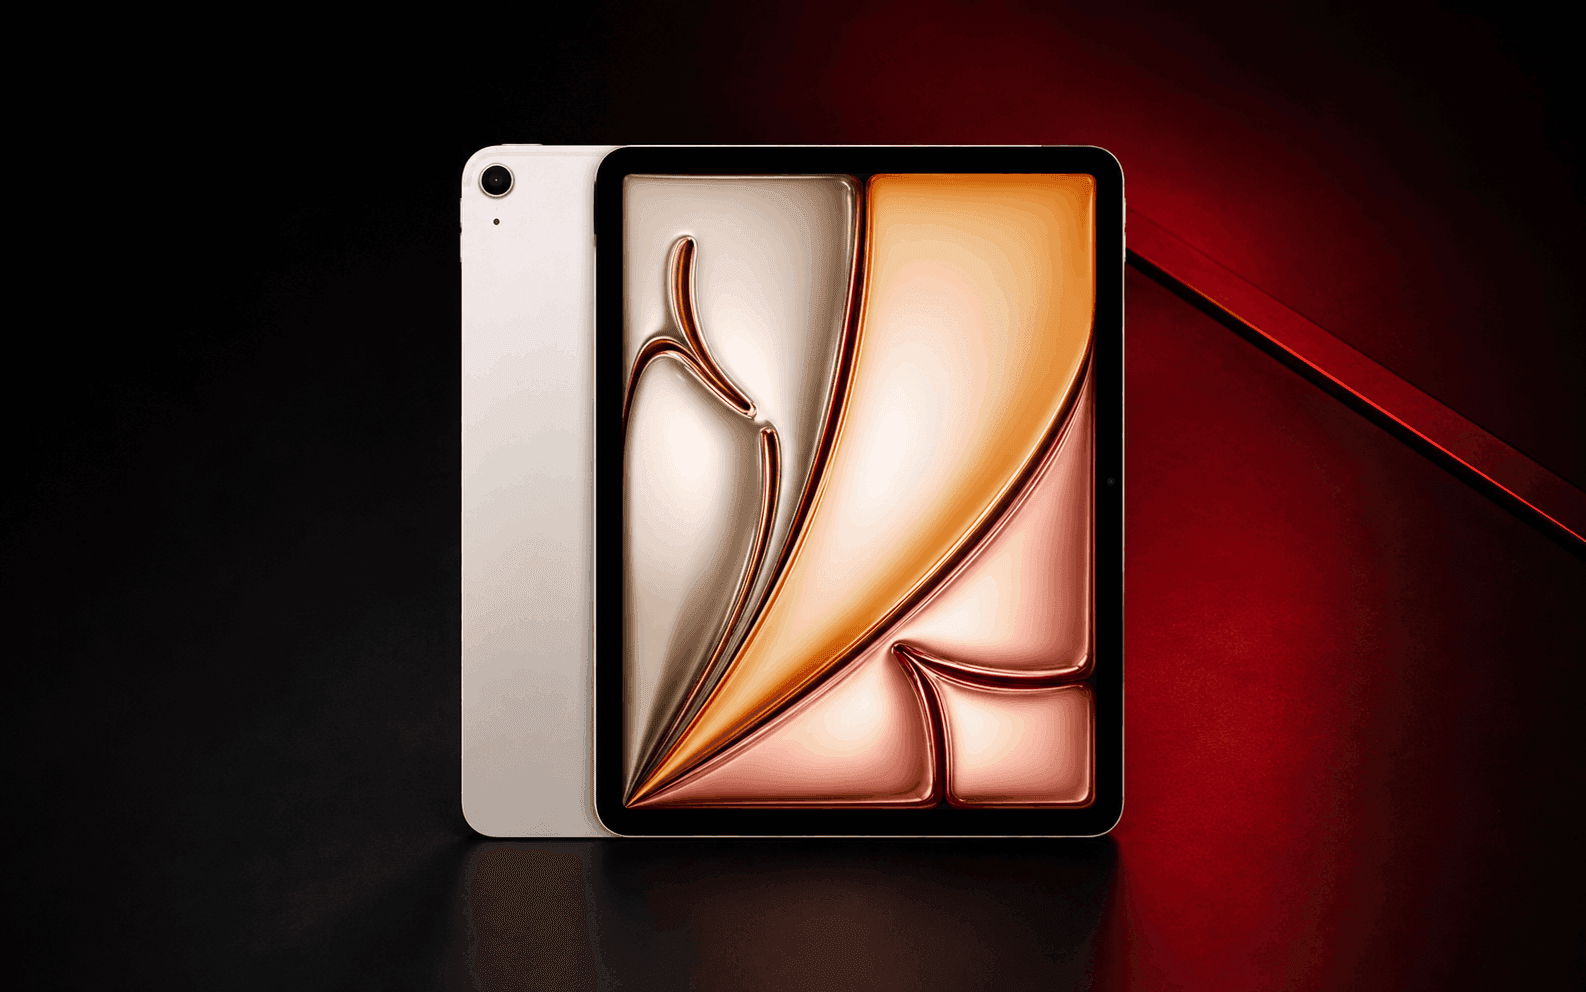
Apple iPad
To every member of the team
Best UI
The project that looks and feels finished. Data is only useful once someone can read it.
Spider-Sense track
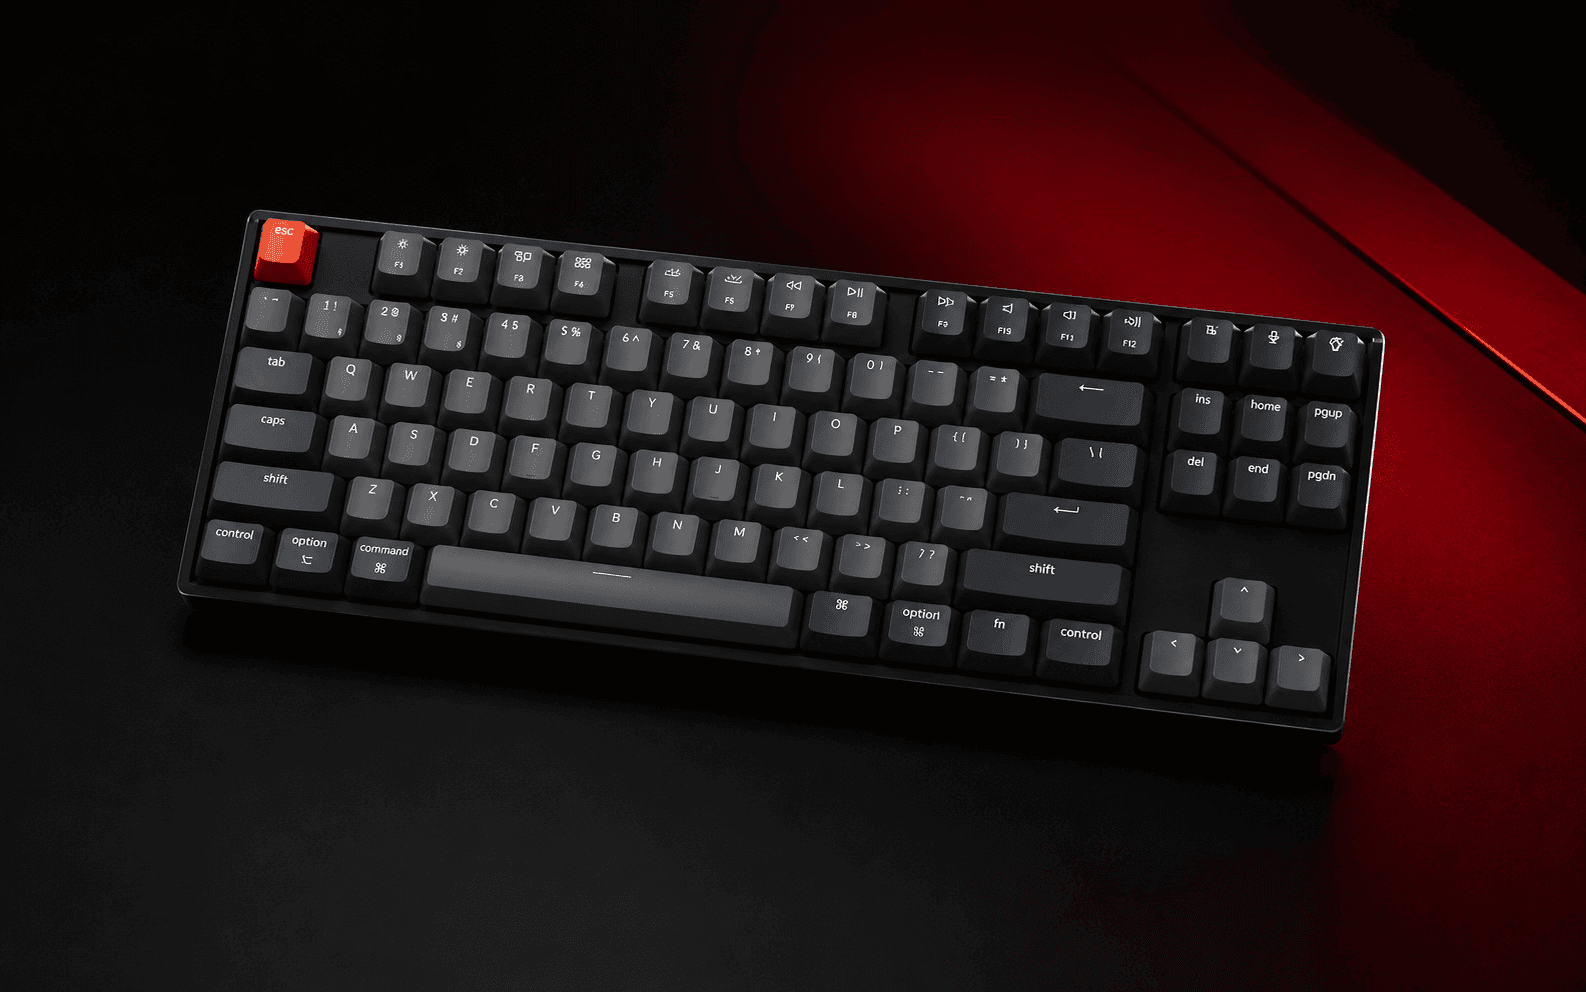
Keychron Keyboard
To every member of the team
Best Clean Code
Readable, structured, and handled at the edges. The repository a stranger could pick up on Monday.
Raffle
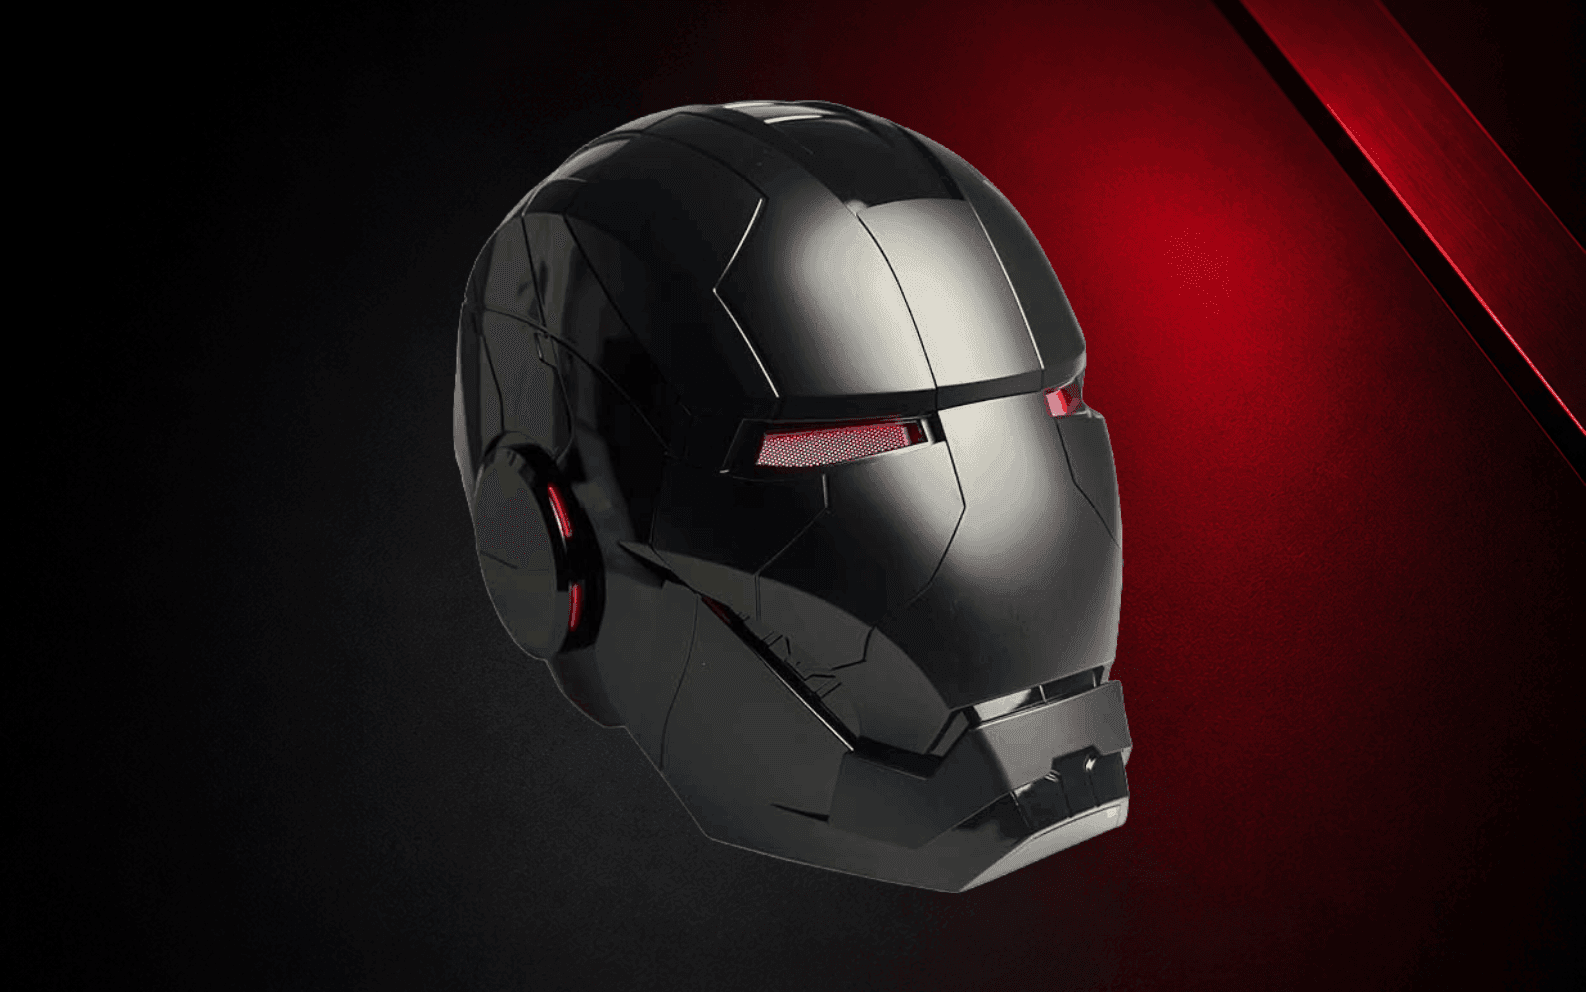
Iron Man MK5 Helmet
To one lucky registration
Drawn from every registration
Black Edition, with voice control, drawn from everyone who signed up. Winning a track, filing a project, and writing a line of code were never conditions of entry.
Top 50 submissions
WeMakeDevs swag for the top 50 submissions
To 50 submissions
You don't have to win a track to come away with something. Every project in the top 50 gets a WeMakeDevs swag pack, so a scraper that runs, a README a stranger can follow and a demo video are worth filing whatever else the week did to your build.
50Swag packs
Daily Bugle track
Samsung Galaxy Watch
To one post
Best LinkedIn Post
Post about what you're building, an experiment that worked, or the story of your hackathon week, and tag WeMakeDevs. LinkedIn only: posts anywhere else don't count.
$2,500 in Bright Data credits
Split across the top teams, so the collectors you built this week keep running long after it ends.
$50 in Bright Data credits
Not a prize and not split between teams: sign up with Bright Data and the $50 is yours to build with.
Nothing on your account? Enter the code wemakedevs in the billing section of your profile. Make sure it's all lowercase.
03 / About
Scrape anything. Break nothing.
Scrapers work in testing, then break quietly the first time a site changes a class name. This week is about fixing that.
example-store.com/laptops
Illustration
Before the redesign
.product-grid > .card .price
Extraction returned nothing
After self-healing
[data-test="price"] > span.amount
1,284 rows recovered
You describe the field once, in plain language. When the page moves, Scraper Studio rewrites the extraction against that description and the collector, c_8f2a91, carries on returning the same shape of data.
01
The page shifts
A class is renamed, a field moves, or the whole layout is redesigned overnight.
02
The scraper notices
Extraction comes back empty where it used to come back with a value.
03
The logic repairs
Scraper Studio rewrites the extraction from a plain-language description of the field.
04
The data keeps flowing
The collector runs on, and nothing downstream of it ever sees a gap.
04 / Getting started
Four commands, and you have a scraper
Bright Data handles the proxies, the retries and the unblocking. You describe the data you want, from the terminal you already have open.
Title sponsor
The web data infrastructure company behind one of the largest proxy and unblocking networks on the internet. Their tool for this hackathon is Scraper Studio, an AI-powered platform for building, running, and self-healing custom web scrapers.
Here's what makes it interesting: you never leave your terminal. The whole thing runs through the Bright Data CLI inside Claude Code, Cursor, or Codex. No global installs, no dashboard hopping, and no proxy rotation, retries, or scraping servers to run yourself.
Pricing is flat at $1.50 per 1,000 page loads, every account gets 5,000 free credits a month, and everyone in this hackathon gets $50 in credits on top.
The AI builds the scraper and hands back a Collector ID.
$bdata scraper run <collector_id> <url> --pretty
Runs it, and returns clean JSON.
$bdata scraper heal <collector_id> "<what broke>"
Repairs the scraper when the site changes under it.
Scraper generation usually takes 5 to 15 minutes, and up to 25 for a complex site. If create isn't instant, it's working.
Two things to know before you build
You own the code
The AI generates scraper code and that code is yours. When the target site changes its HTML, bdata scraper heal fixes it from one prompt: same Collector ID, nothing downstream breaks. This is the differentiator, and it's what we want to see in your projects.
Every scraper is instantly an API
The c_* Collector ID your agent gets back is a production endpoint, triggerable with POST /dca/trigger from any language or scheduler. There is no deployment step.
01
Create a Bright Data account
The free tier is 5,000 credits a month, and it takes no card.
Sign up with Bright Data and the $50 is yours to build with, on top of Scraper Studio's free tier.
Signed up and nothing showing? Enter the code wemakedevs in the billing section of your profile. Make sure it's all lowercase. Still nothing? Email contact@wemakedevs.org and we'll sort it out.
The theme is open-ended: build anything that turns websites into structured data. Each idea names the scraper type it needs.
One-prompt scraper
01
Paste one prompt into your coding agent, point it at a site, and get clean JSON back. Then build something small on top: a CLI tool, a Discord bot, a simple dashboard.
Easiest startPDP or Discovery
Prompt-to-production pipeline
02
Have your agent build the scraper and the pipeline that feeds on it: a script that triggers the Collector ID, saves the JSON to storage or a database, and runs on a schedule. One prompt, one PR, fresh data every night.
Discovery + PDP
Set a goal and walk away
03
Give your agent a goal, like scraping a site every day at 3am and saving the results to storage, and let it plan, build, schedule, and verify the whole thing end to end.
Discovery + PDP
Self-healing scraper
04
Every scraping tutorial ends when the scraper runs. Make yours start when it breaks: build one, break it or catch a real site change, heal it from a description of what broke, and re-run. Bonus points for automating the whole loop.
Hero projectAny type
Scrapers in CI, no humans
05
Put a scraper run inside GitHub Actions on a cron. When the target site changes, have your agent heal it and re-run the job on its own. A scraper that fixes itself while you sleep, with a wall of green checks to prove it.
Any type
Docs site to RAG pipeline
06
Point a Sitemap scraper at any documentation site and get every page as structured JSON. Chunk it, embed it, and build a chat-with-these-docs app that answers with real citations.
Sitemap
Competitive intel pipeline
07
Scrape three to five competitor changelogs every week, diff the results against last week, and deliver what changed to your inbox, Slack, or Discord every Monday.
Sitemap
Keyword-powered agent
08
The Search scraper type needs a keyword and an optional country, with no URL at all. Build an agent that researches products, prices, jobs, or listings on demand from a plain-English request.
Search
Parallel subagents battle
09
Spin up three subagents in three git worktrees, each building a scraper for a different site, then have a fourth judge the outputs and ship the winner.
Any type
Short on time
1 or 4
Want a production story
2, 3, or 5
Into AI and RAG
6 or 8
Want to stand out
4, 5, or 9
What you're expected to do
Build a working project with Bright Data Scraper Studio at its core, with at least one real create and run flow. Your c_* Collector ID is the proof.
Demonstrate self-healing with bdata scraper heal if you can. Judges will be looking for it.
Wire your Collector ID into something real downstream: an API trigger, a schedule, a database, an agent, or a dashboard.
Scrape publicly available data only, and pick sites that Bright Data's pre-built library doesn't already cover.
Submit a repository with clear setup instructions, so a judge can clone it and reproduce what you built.
06 / Best practices
How to spend the week well
Five rules from the people who built the platform. The first one decides whether a project qualifies at all.
01
Build for the long tail, not against pre-built scrapers
Bright Data already has a library of 800+ pre-built scrapers for the big sites. If your target is in there, pick a different one. Scraper Studio is for everything else: regional e-commerce, B2B catalogues, niche verticals, docs sites, competitor changelogs. Quick test, if a judge would ask why you didn't just use the pre-built scraper, change your target.
02
The terminal is the UI
Do the whole workflow from inside your coding agent. The dashboard is for a glance to confirm your Collector ID exists, or to set a schedule. If your project needs three dashboard tabs open, something has gone wrong.
03
Code ownership plus self-healing is the point
The combination is what makes this different: you own the scraper code, and the AI repairs it when the target site changes. Show bdata scraper heal working, in the project or in the demo video. Same Collector ID, nothing downstream touched. This is what judges will look for.
04
Scrape publicly available data only
No login-walled sites, no paywalled content, no personal data. Public pages only. And keep your API tokens and your .env out of the repository and out of the demo video: mask them, or use a throwaway key.
05
The Collector ID is your production API
Every scraper returns a c_* Collector ID you can trigger with POST /dca/trigger from any language or scheduler, with no deployment step. Wire it into something real: a cron job, a database, an agent, a dashboard. Projects that treat it as a live endpoint will stand out.
07 / Judging
What the judges are looking for
Six criteria, weighted equally. The demo is scored as hard as the code.
01
Potential impact
Does the project solve a clear and useful problem?
02
Creativity and innovation
Does the project approach web-data collection in an original way?
03
Technical excellence
Is the implementation complete, reliable, and well structured?
04
Use of Scraper Studio
Is Bright Data Scraper Studio central to the project?
05
Reliability and self-healing
Does the project account for website changes, missing data, or extraction failures?
06
Presentation
Does the demo clearly explain the problem, scraper workflow, structured output, and final product?
08 / FAQs
Got questions?
Is it in person or online?
You can take part online or join us in person in San Francisco. Whatever works for you!
Can I still register?
No. Registration ran on a Google Form and it closed with the hackathon on August 23, along with the submission form.
Is Scraper Studio mandatory?
Yes. Every eligible project must use Bright Data Scraper Studio.
Where can I find resources to learn more about the tools?
Every tool, guide, and tutorial you need is collected on one page. Browse the resources.
Does everyone on a winning team get the prize?
On the iPad and Keychron tracks, yes: every member of the winning team gets one, not one representative. The grand prize is a single NVIDIA DGX Spark awarded to the winning team.
Does it cost anything to use Scraper Studio?
No. Every participant gets $50 in Bright Data credits to build with, on top of Scraper Studio's free tier of 5,000 credits a month. Run out before you ship and we'll top you up. Email contact@wemakedevs.org.
How do I get my $50 in credits?
Sign up for Bright Data, open the billing section of your profile, and enter the promo code wemakedevs. Make sure it's all lowercase. The $50 is credited to your account. Sign up for Bright Data.
I signed up but I don't have any credits. What now?
The credits come from the promo code, so signing up on its own doesn't grant them. You don't need a second account: open the billing section of your Bright Data profile, enter the code wemakedevs, and the $50 is credited to the account you already have. Make sure the code is all lowercase. Still nothing? Email us and we'll sort it out. Email contact@wemakedevs.org.
Can I enter more than one track?
Every submission is considered for the grand prize and both project tracks automatically. There's nothing extra to file and nothing to opt into. The Daily Bugle track is the one exception: you enter it by posting.
How do I win the Samsung Galaxy Watch?
Post on LinkedIn about what you're building, an experiment that worked, or your hackathon week, and tag WeMakeDevs. The best post takes the watch. It has to be LinkedIn, and you can post as often as you like during the week.
How does the raffle work?
Every registration went into it, and one is drawn now that the hackathon has closed. The winner gets the Iron Man MK5 helmet. Building a project was not a condition of entry.
Can I use AI coding tools?
Yes. You may use coding agents and AI development tools. You must understand the submitted project, verify the generated code, and be able to explain your technical decisions.
What websites can I scrape?
Use publicly available web data. Do not scrape private, login-protected, paywalled, or restricted information.
Can I still submit my project?
No. Submissions closed with the hackathon on August 23 and the form is no longer taking entries. Results go out on the Discord and across our socials in early September.
In person · San Francisco
Zero Downtime was the in-person half of this hackathon: one day in San Francisco on August 22, same brief and same sponsor, run with Bright Data. The photographs at the top of this page are from that morning.